Sliced Word Embeddings Association Test
The Sliced Word Embedding Association Test (SWEAT) is a statistical measure of relative semantic polarization for pairs of textual corpora.
The measure relies on aligned distributional representations for the elements of each corpora vocabulary, specifically aligned Word2Vec gensim models such as those obtained through CADE are assumed in this implementation. While any pair of Word2Vec models can be used, alignment is necessary to ensure that the two distributional representations are comparable.
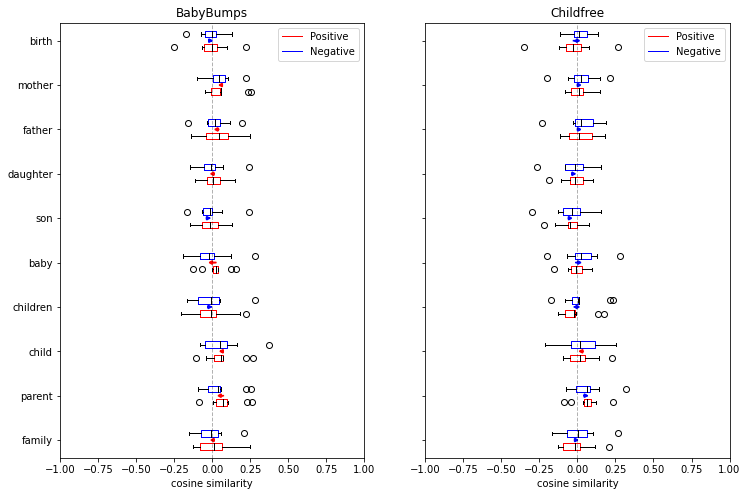
The SWEAT is an extension of the Word Embedding Association Test (WEAT) proposed by Caliskan et al. (2017): while the WEAT measured the comparative polarization for a pair of topical wordsets (e.g. insects and flowers) against a pair of attribute wordsets (e.g. pleasant and unpleasant) in a single-corpus distributional model (e.g. 1950 american newspaper articles) the SWEAT measures the relative polarization for a single topical wordset (e.g. parenting) against a pair of stable attribute wordsets (e.g. positive and negative sentiment valence) in a pair of aligned distributional models from two different corpora (e.g. r/childfree and r/BabyBumps).